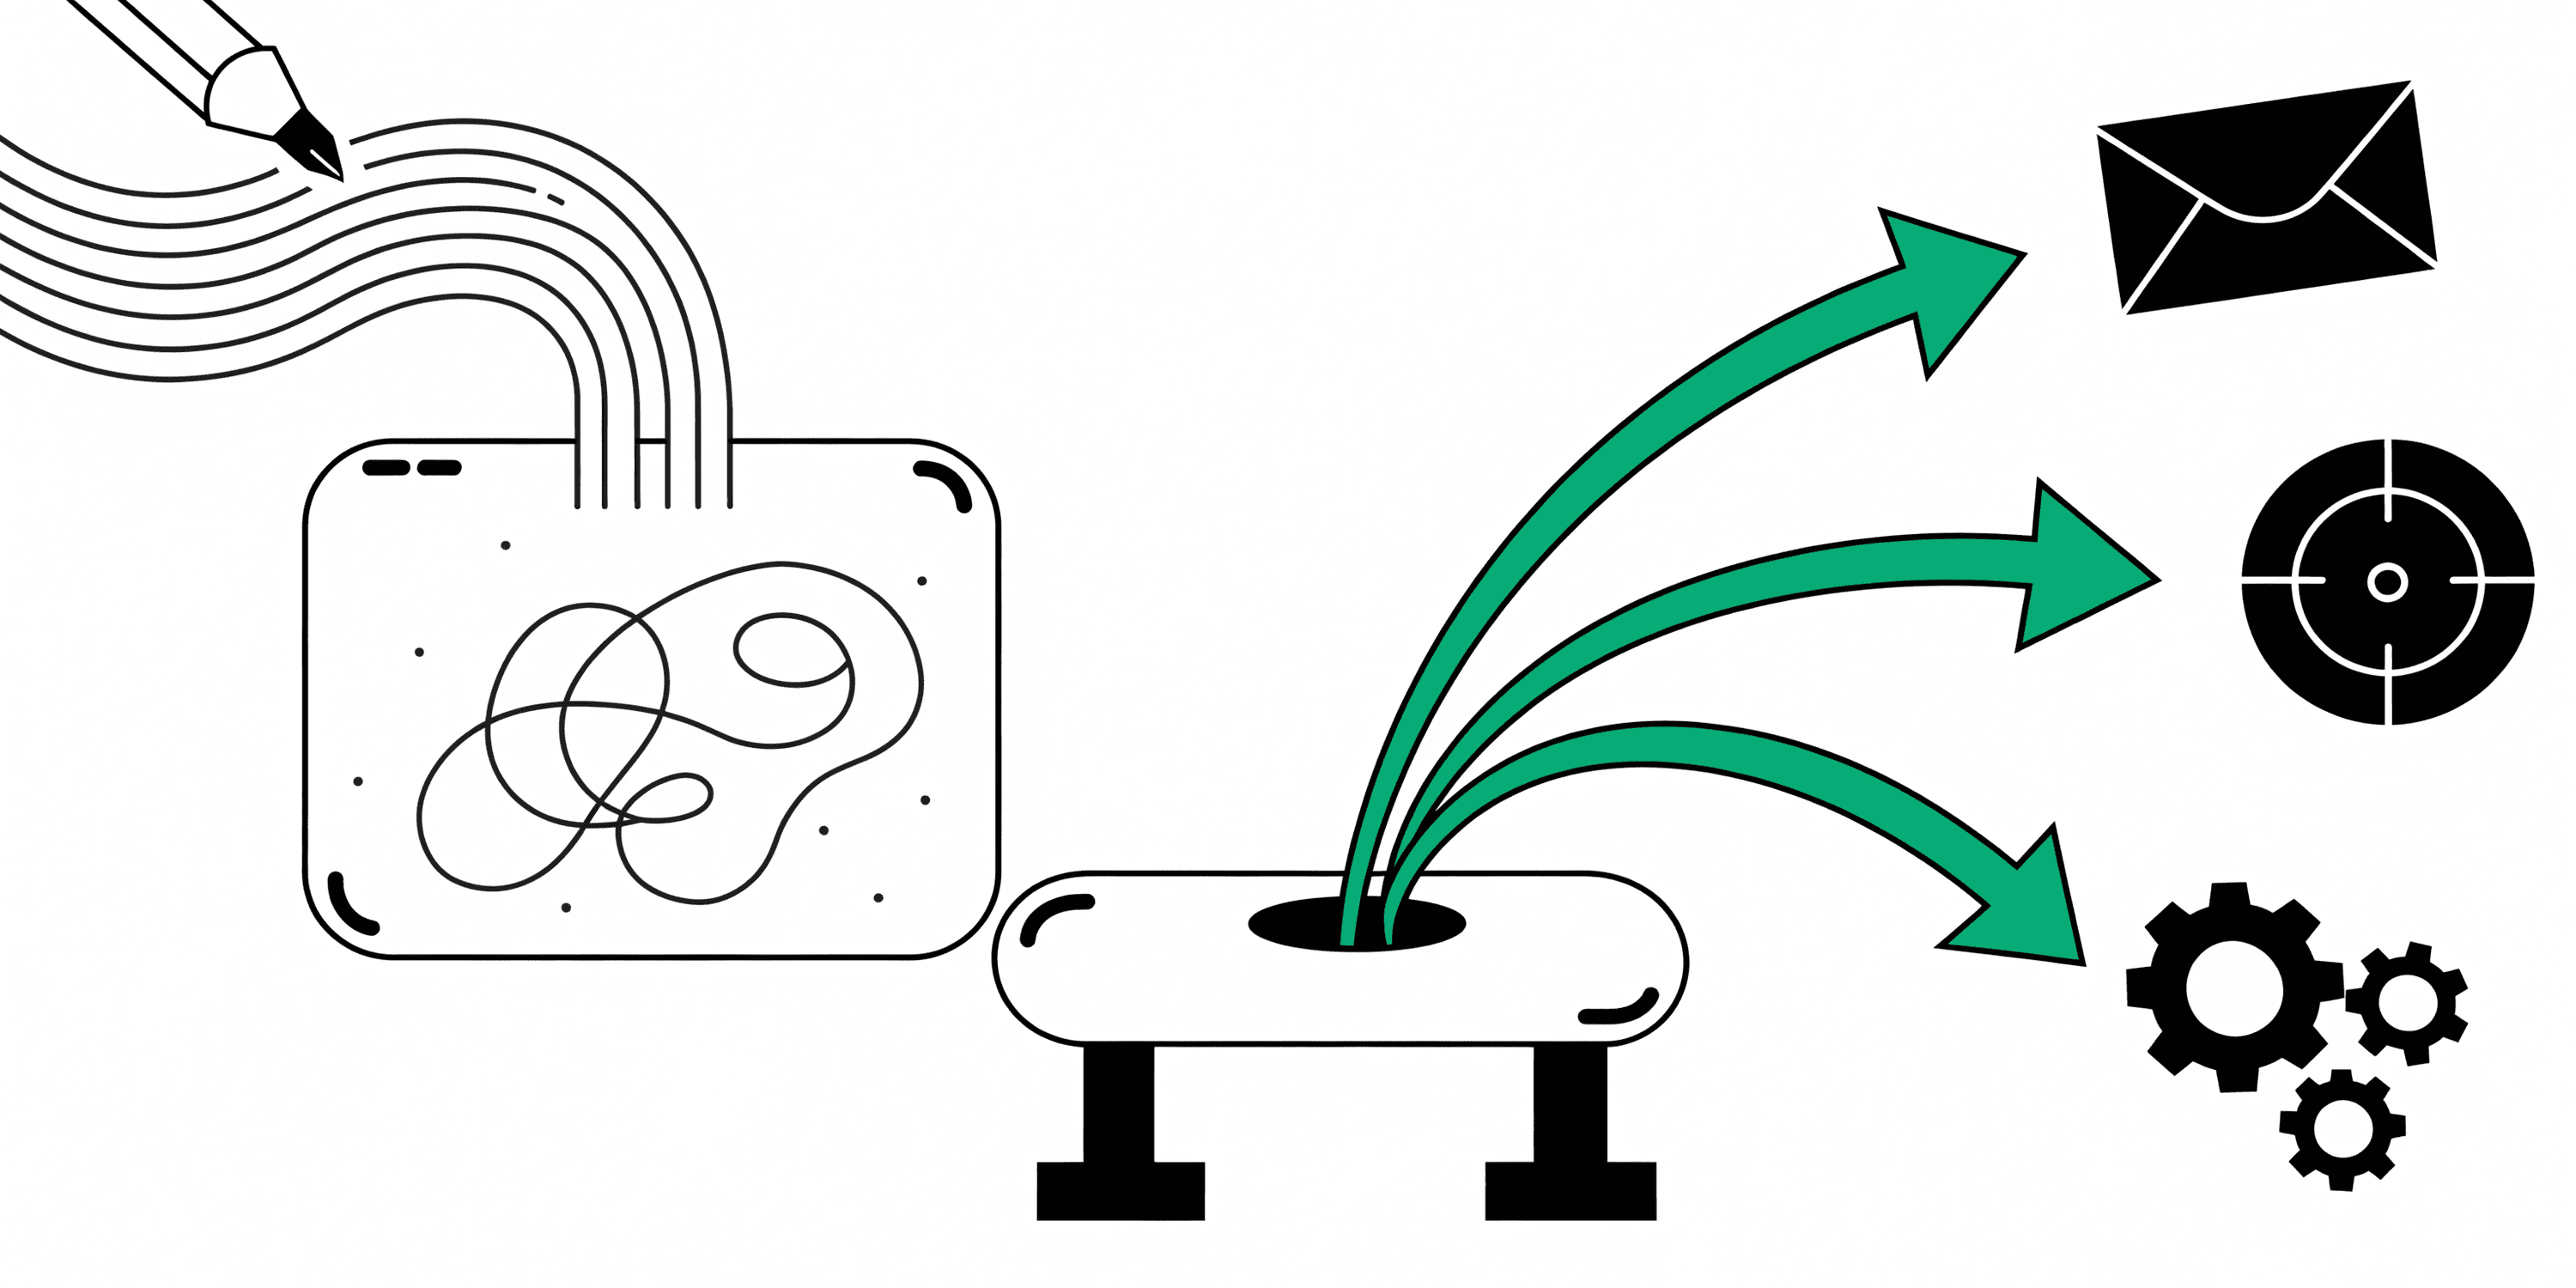
- Customer data integration is getting every tool that knows something about a customer to agree on who that customer is. Moving fields between tools is the easy half. The hard half is keeping the identity attached while the data moves.
- One-way connectors copy fields and drop identity, so you end up with the same person living as four slightly different records. Two-way sync fixes that by resolving everything into one profile first, then writing the result back to the tools your team already works in.
- Before you turn on any write-back, decide what each connection may read and write, check consent, and clean up duplicates. Then start with one field, like lifecycle stage in your CRM, and grow from there.
Customer data integration sounds like a plumbing problem, and honestly it mostly is one, but it's the kind of plumbing where a small leak quietly ruins every campaign you run on top of it.
Here's the thing I keep seeing. A team has a CRM, a store, an email tool and some analytics. Each one is fine on its own. Then someone asks a simple question like "how many of our trial users came from that ad and then paid" and nobody can answer it without a spreadsheet and an afternoon.
That's not a tool problem. It's that four systems each hold a slightly different version of the same customer. If you want the wider view of how stacks end up like this, the GTM stack guide covers why the real cost sits in the connections between tools, not the licenses. This post is about the connections themselves.
What customer data integration actually means
It means getting every tool that knows something about a customer to agree on who that customer is. That breaks down into three jobs, and most setups only do the first one well.
- Collect. Pull events and fields from your CRM, store, email tool, product and billing.
- Resolve. Match all of it to one person, so a work email, a personal email and a device ID end up on one record.
- Sync back. Push the combined result, like a segment or a lifecycle stage, back to the tools your team actually works in.
Collecting is the easy part. Resolving is where it gets hard. Syncing back is the part people skip, and it's the part that makes the whole thing useful, because nobody on your sales team is going to open a separate data tool to check a field.
Why one-way connectors leave you with four versions of one customer
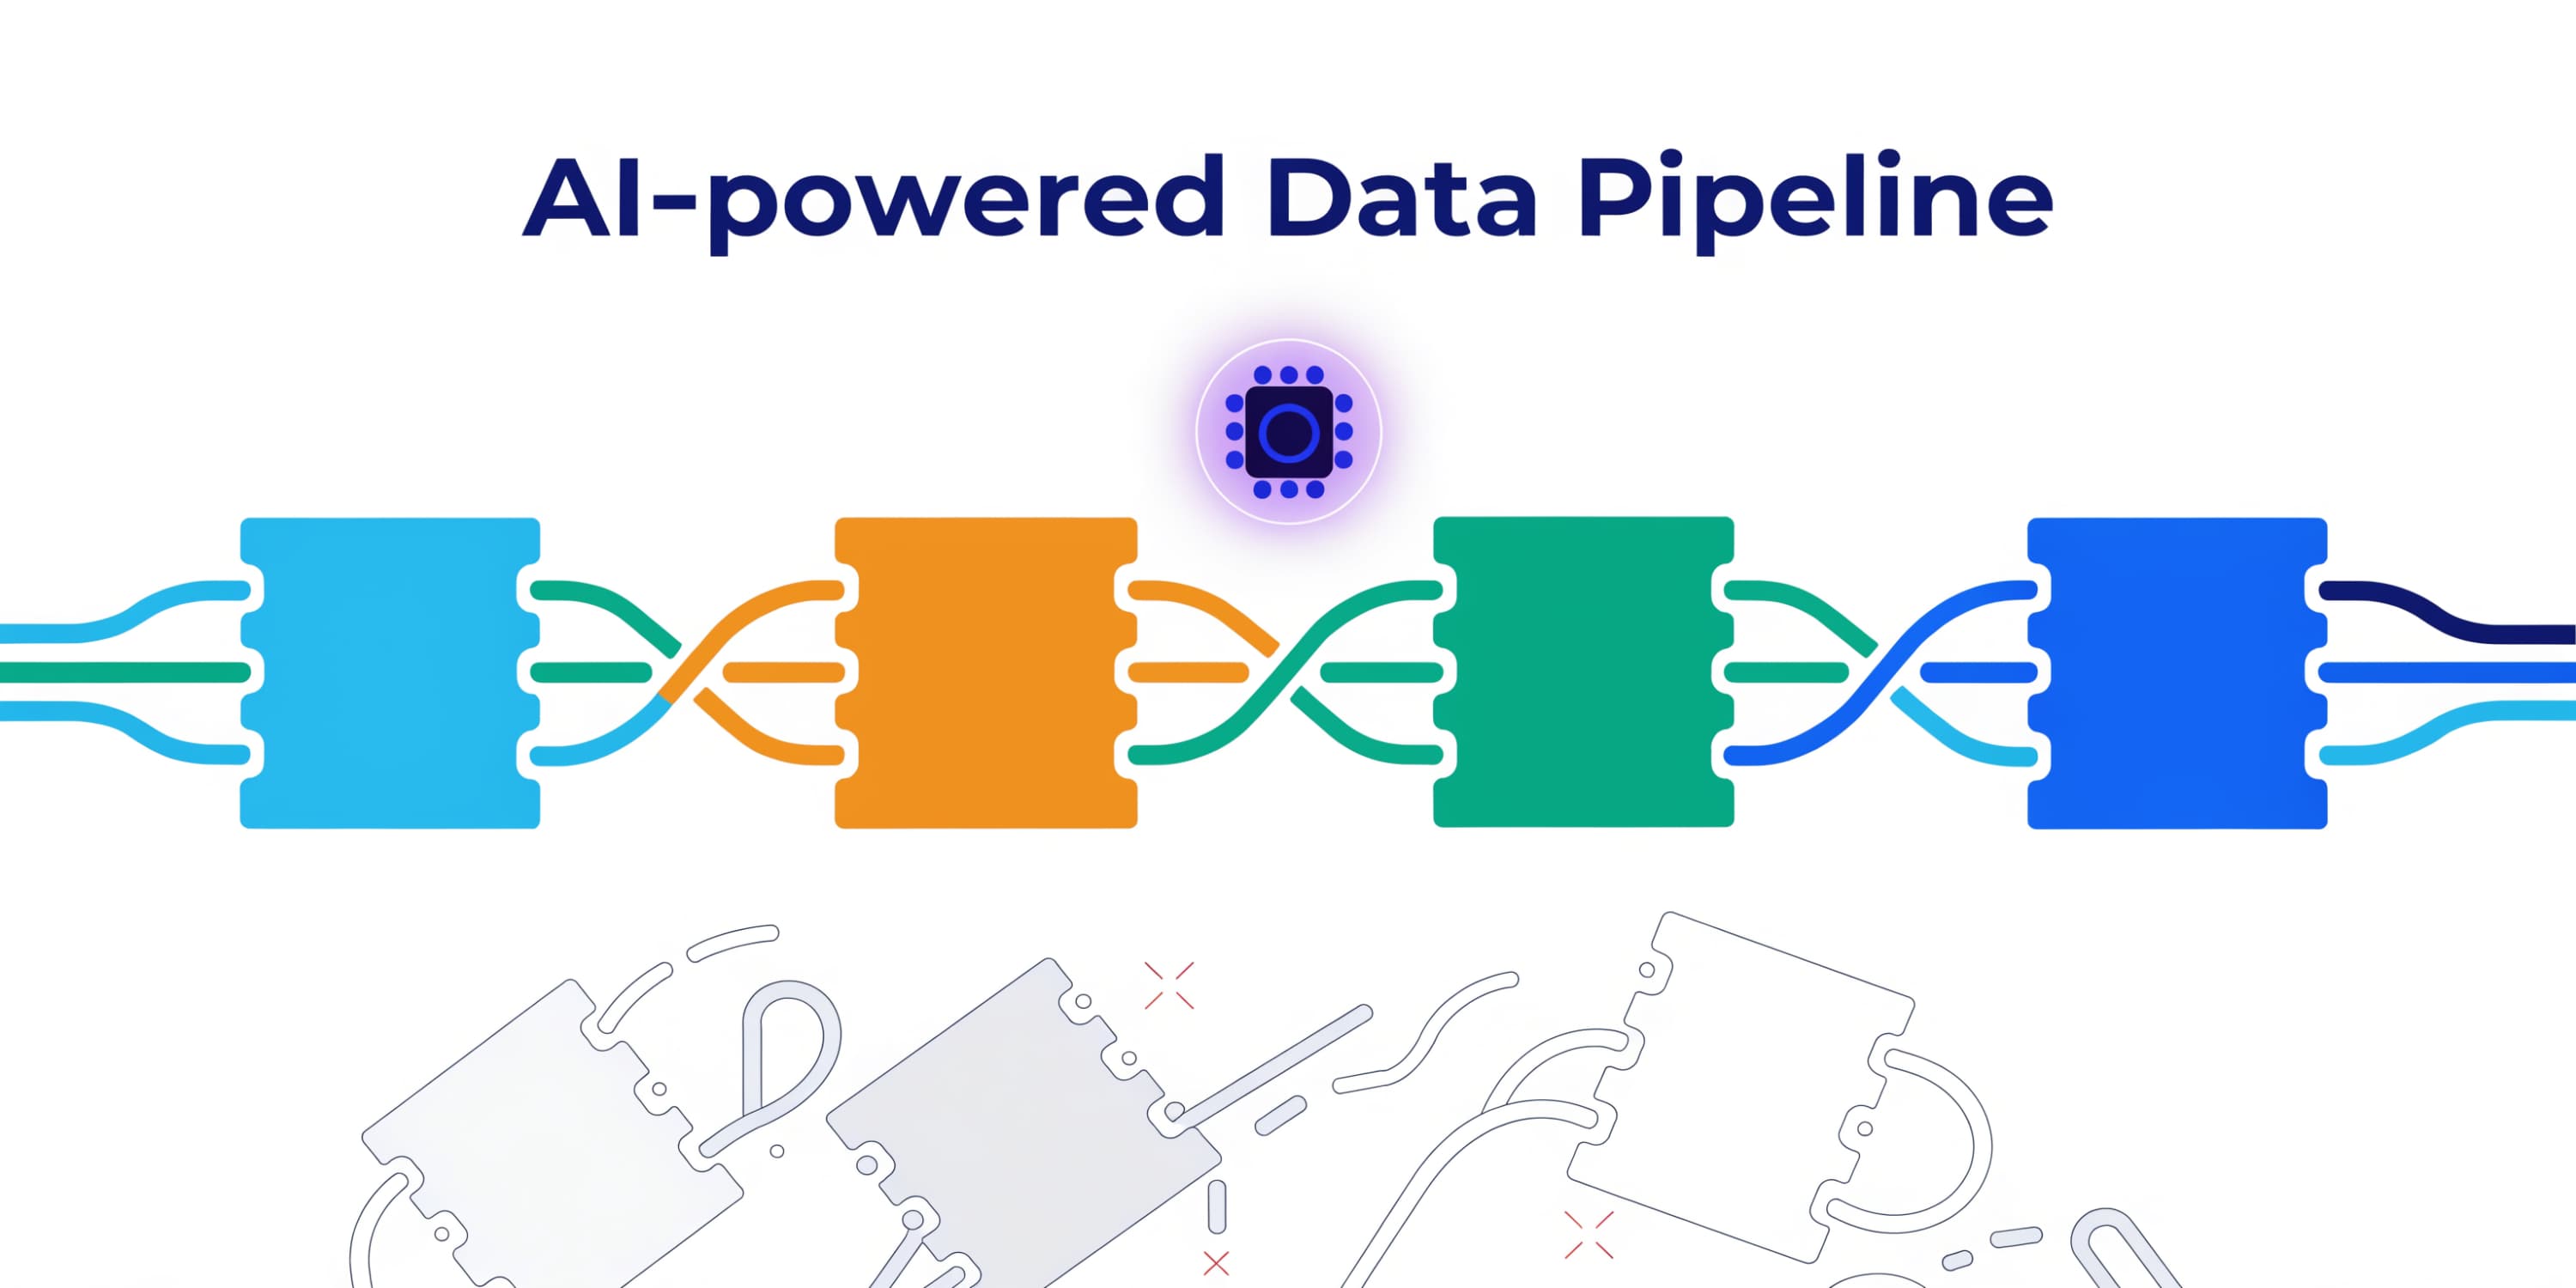
A connector moves fields from tool A to tool B. That's it. It usually doesn't know that the person in tool A is the same person already sitting in tool B under a different email, so it either makes a new record or overwrites the wrong one.
Stack three or four of those point-to-point syncs and you get what most teams have now: HubSpot free plus Mailchimp plus Calendly plus GA4, joined with duct tape. Three seams, and no single view of ad click to signup to trial to paid, because every seam drops a bit of identity on the way through.
The fix isn't another connector. It's changing the order: resolve identity first, into one profile, and only then send data anywhere.
How two-way sync works
Two-way sync means data flows in from your tools and the results flow back out, with one resolved profile in the middle. Here's the loop in order.
- Read. Each connected tool sends its changes in. A new deal stage in the CRM, an order in the store, a login in the product.
- Resolve. Every change lands on one profile, matched to the right person, on one shared set of field names.
- Compute. Segments, lifecycle stages and scores update on that profile, because now they can see everything the person did.
- Write back. The result goes back to the tools that need it, only into the fields you allowed, so your CRM shows the real lifecycle stage without anyone exporting a list.
The write-back step is the one that changes how people work. When the lifecycle stage in your CRM is computed from actual product and billing behaviour, sales stops arguing with marketing about who counts as a lead, because the field is just true.
One field to start with: lifecycle stage in your CRM
If you only sync one thing back, make it lifecycle stage. It's one field, everyone understands it, and it's easy to check whether it's right. The HubSpot lifecycle write-back recipe pushes the stage computed from real product and billing behaviour onto the HubSpot contact.
Billing is the next easy win. The Stripe subscription sync recipe keeps plan, status, revenue and renewal dates in step on every profile, so a churn-risk segment is looking at what customers actually pay, not what someone typed into the CRM last quarter.
What to check before you turn on a write
Reading data is low risk. Writing it back is where you want a few guardrails, because a bad write shows up in front of your sales team the next morning.
| Check | Why it matters |
|---|---|
| Which tool owns each field | Two tools both writing the same field will fight forever. Pick one source of truth per field. |
| What each connection may read and write | Declare it up front. A sync should only ever touch the fields you allowed. |
| Consent | A person who opted out in one tool has opted out everywhere. Check before any send. |
| Duplicates | Merging after you sync is painful. Clean up duplicate contacts first. |
| Field changes | If a synced field changes shape, you want to know which segments depend on it before a write breaks them. |
Duplicates are the one people underestimate. The CRM record merge recipe checks new accounts and contacts against what you already have, merges the obvious ones and queues the rest for a person to decide.
Customer data integration vs a CDP vs ETL
These three get mixed up a lot, so here's the short version. One is a job, the other two are ways of doing parts of it.
| What it is | What it leaves to you | |
|---|---|---|
| Customer data integration | The job: one accurate profile per customer, shared by every tool | Nothing, it's the goal |
| ETL tool | Moves data between systems on a schedule, usually into a warehouse | Identity matching and writing results back to your tools |
| Customer data platform | Collects data, resolves identity and syncs segments out in one system | Deciding which fields move and who owns them |
If you already run a warehouse, you don't have to pick. You can keep it as the place analysts query and still use two-way sync for the fields your GTM tools need day to day.
Where Intempt fits
This is the problem Intempt integrations are built around. The library has 26 sources and 13 destinations. HubSpot, Shopify and Stripe are live sources today, with more in review, and HubSpot also runs back out as a destination, so the lifecycle stage above can land on the contact. Everything lands on one resolved profile, and every product reads that same profile, so segments, journeys, analytics and pipeline all agree.
Most connections are one-click OAuth. You declare what each one may read and write, and the Data Engineer agent stays inside that: it publishes only to declared destinations, checks consent before a send, and flags when a synced field changes shape. The profile itself lives in the Data Hub, and it's part of the agentic GTM platform your other agents work from.
If you run a warehouse, Intempt writes Parquet into a bucket you own for the warehouse to read, and publishes to Kafka topics you declare.
Where to start this week
Don't try to connect everything on day one. Do it in this order.
- List your tools and write down which one owns each important field.
- Clean up duplicate contacts in your CRM.
- Connect your CRM and one more source, usually the store or billing.
- Turn on one write-back, lifecycle stage, and check it by hand for a week.
- Add the next field only once you trust the first one.
That's really it. Good customer data integration isn't about how many tools you connect, it's about whether they all agree on who your customer is.
Frequently asked questions.Answered.
- Customer data integration is the work of pulling customer data from every tool you use, matching it to the right person, and keeping one current profile that every tool can read. It covers three jobs: collecting the data, resolving identity so one person is one record, and syncing the result back out.